Browser Agents: Build Reliable Web Automation
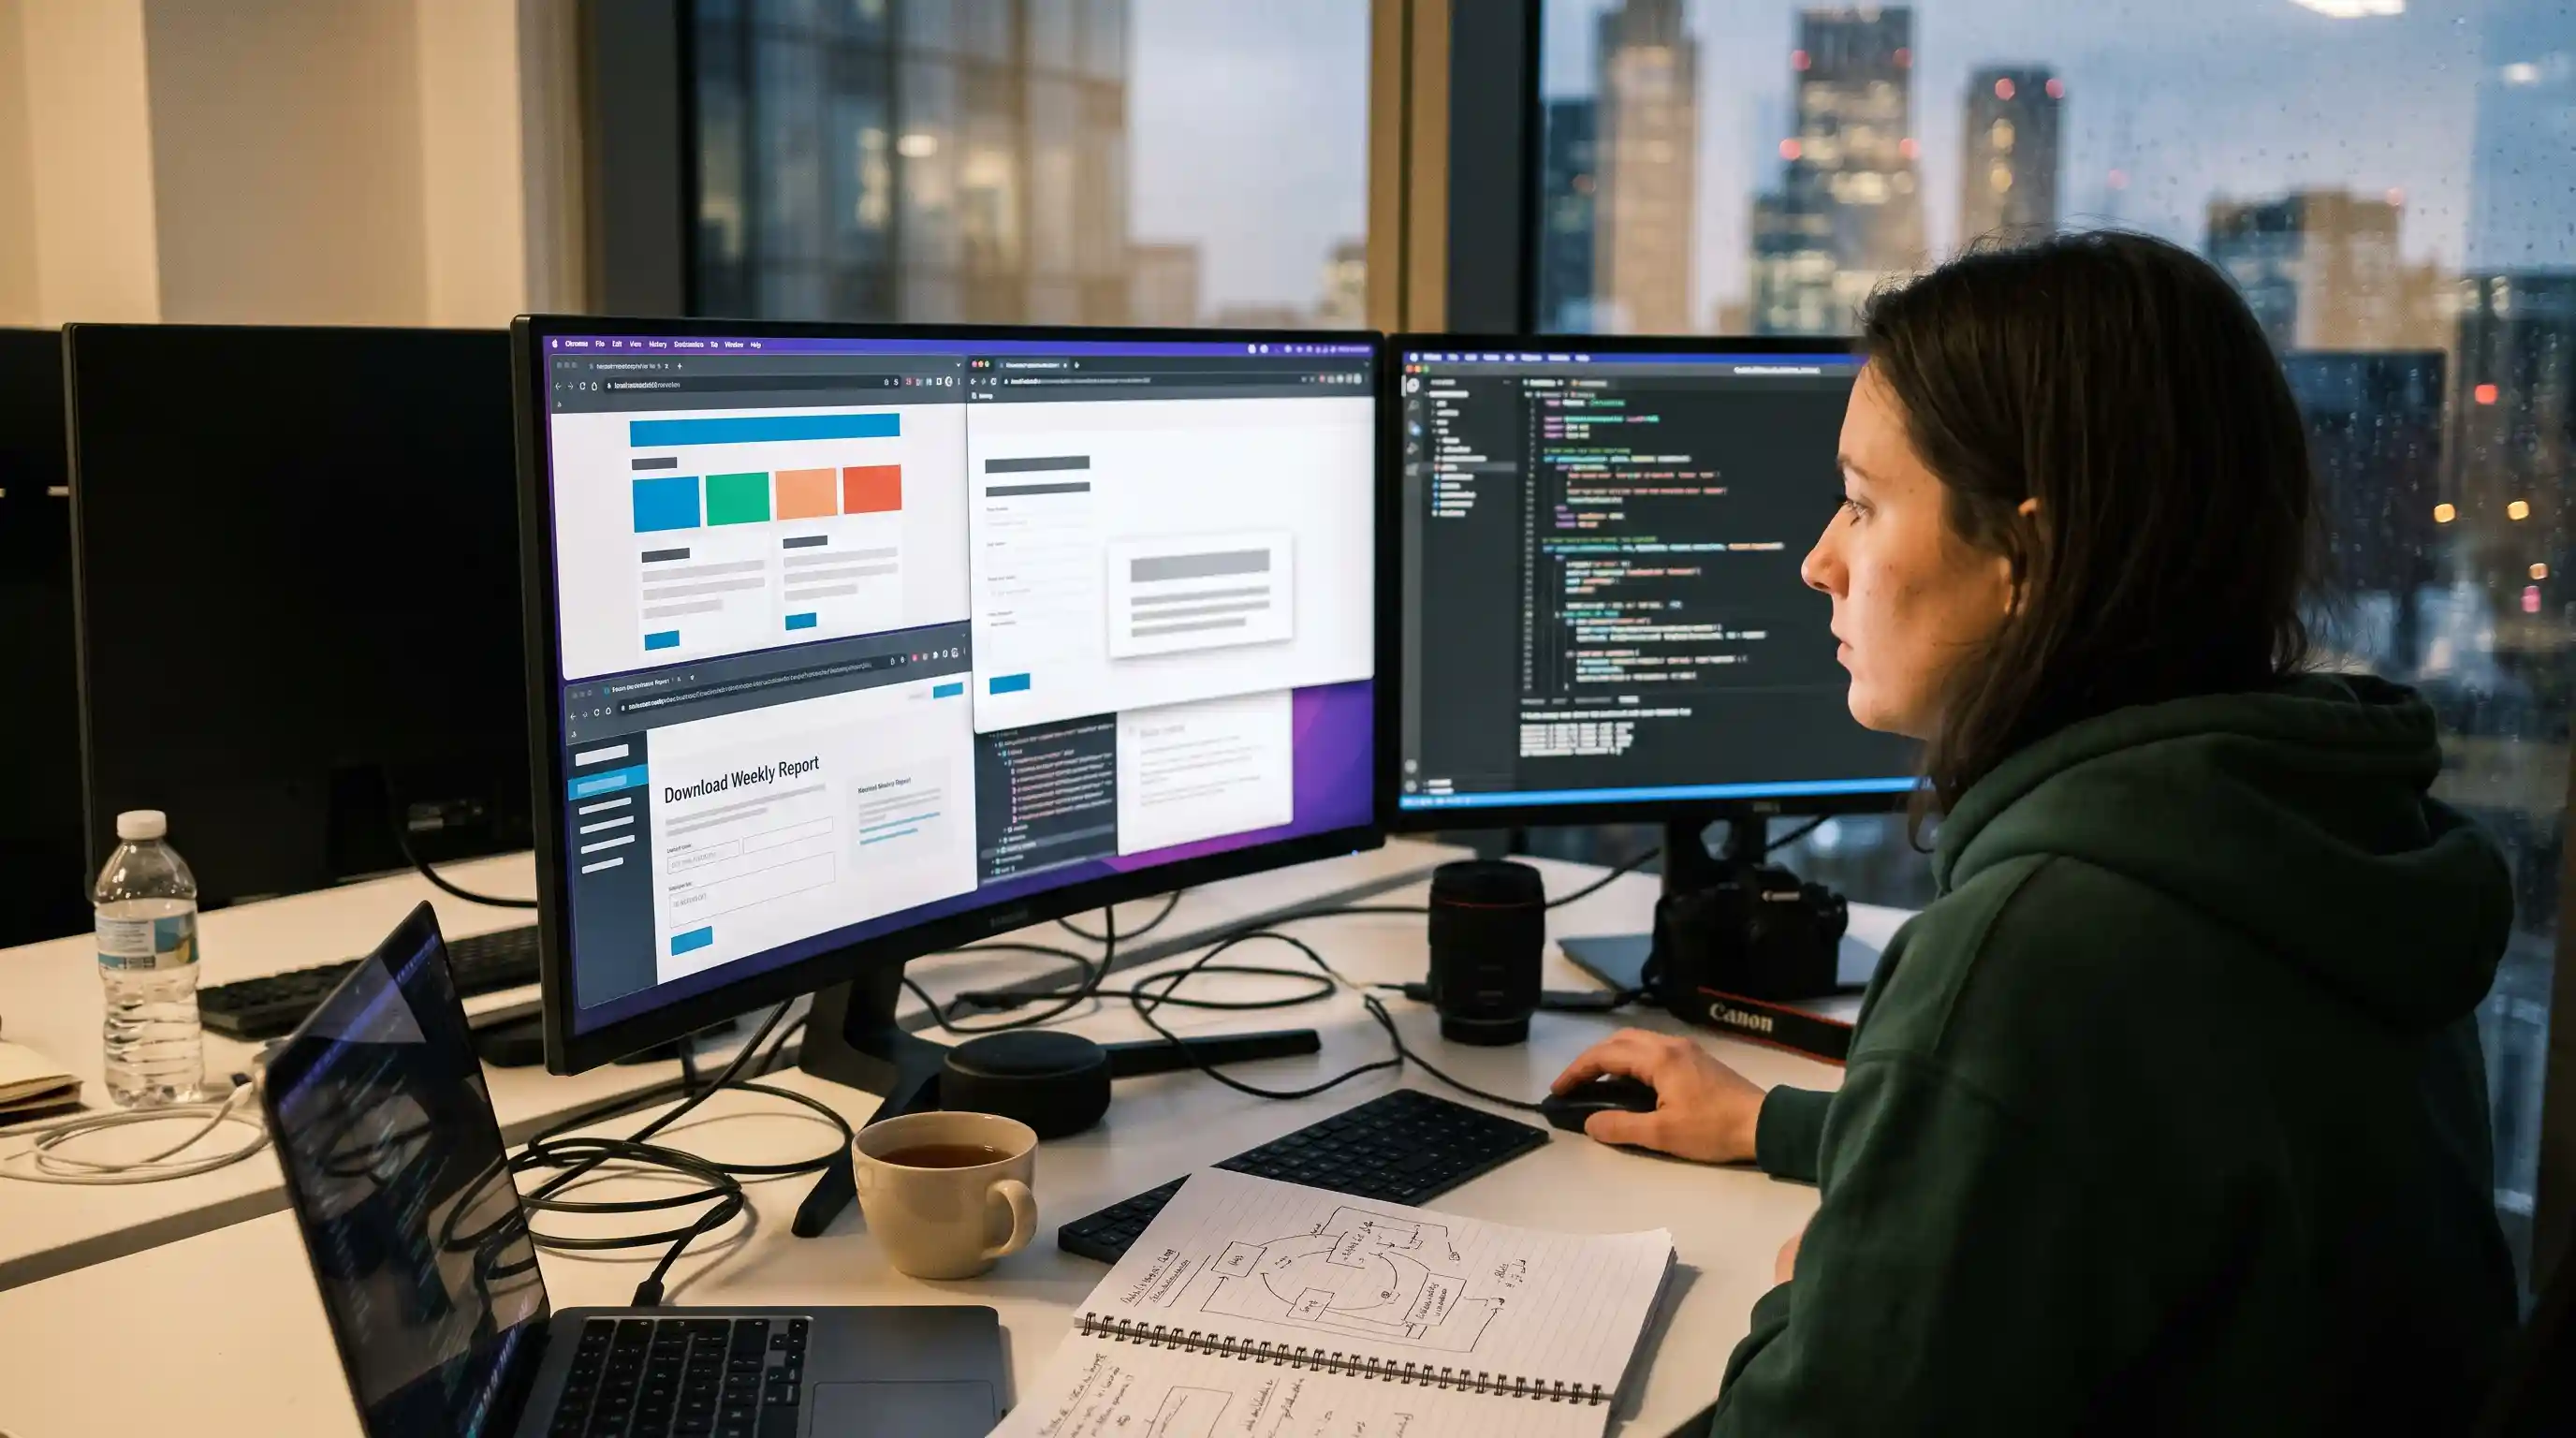
- The Core Shift: Moving from brittle CSS selectors (Selenium) to semantic goal-driven navigation (Agents).
- Architecture: A continuous perception-action loop relying on DOM stripping, bounding boxes, or direct vision APIs.
- Top Frameworks: Open-source
browser-usedominates Python builds, while Claude’s computer use API sets the standard for direct screen control. - Security Threat: Exposing an agent to the open web makes it a massive target for indirect prompt injection. Sandboxing is non-negotiable.
Building an LLM that can chat is a solved problem. Building an agent that can reliably navigate a dynamic, JavaScript-heavy web application without breaking on the third click is an engineering nightmare.
Traditional RPA and Selenium scripts shatter the moment a UI layout changes, forcing developers to look toward autonomous browser and computer-use agents.
However, out-of-the-box browser and computer-use agents often fail in production, getting stuck in infinite loops or hallucinating DOM elements that don't exist.
This guide breaks down how to build resilient web automation agents, comparing raw DOM-parsing approaches against vision-based computer use to give you a reliable architecture that scales.
1. The Architecture of Browser & Computer-Use Agents
Unlike standard orchestration agents that rely on structured API endpoints, a browser agent interacts with unstructured human interfaces. This requires a robust perception-action loop.
The agent must "perceive" the screen, reason about its goal, predict an action (click, type, scroll), execute it, and then evaluate the new state.
There are two dominant ways to handle perception. The first is DOM-based, where the agent parses a simplified HTML tree, mapping interactable elements to numerical IDs.
The second is vision-based computer use, where a multimodal LLM takes a screenshot, calculates pixel coordinates, and fires synthetic mouse events. To understand the tradeoffs and set up your own perception loop, read our technical breakdown on how to build a browser agent that doesn't break.
2. Building with browser-use (Python)
For Python developers, the open-source browser-use library has emerged as the fastest way to wrap an LLM around a Playwright instance.
By abstracting away the raw DOM manipulation, it allows you to pass high-level goals like "Log into this portal and download the latest invoice" directly to models like GPT-4o or Claude 3.5 Sonnet.
However, running this headless in production requires explicit handling of authentication states and dynamic waits.
We've published the exact code required to wire this up, including error recovery, in our browser-use in Python example.
3. Claude Computer Use and Project Mariner
While browser-use drives the DOM, Anthropic’s computer use API interacts with the OS directly. By utilizing custom tools, Claude can look at a screenshot, determine the X/Y coordinates of a button, and move the cursor.
This breaks the agent out of the browser, allowing it to interact with native desktop applications. Follow our Claude computer use tutorial to see a sandboxed implementation.
Simultaneously, Google is pushing the boundary with its own ecosystem. Project Mariner represents an attempt to bake agentic browsing directly into the Chrome architecture, leveraging Gemini’s multimodal speed.
We break down its capabilities and release trajectory in Project Mariner explained.
4. Information Gain: Why Browser Agents Fail in Prod
Demoing an agent booking a flight on a pristine test site is easy. Running an agent across 1,000 messy enterprise portals is where the illusion shatters.
The primary reason browser agents fail is UI drift and asynchronous loading. If an LLM predicts an action before a React component finishes hydrating, the click goes into the void, and the LLM enters a hallucination loop attempting to recover.
Furthermore, vision models frequently struggle with high-density UIs, often misclicking by a few pixels on tightly packed data tables.
Stop relying on blind retries. Learn how to implement multi-step verification and strict boundary limits in our guide on why browser agents fail.
5. Security: The Prompt-Injection Threat Surface
Exposing a computer-use agent to the live web is the highest-risk architecture you can deploy. An attacker can place invisible white text on a webpage containing malicious instructions.
Because the agent reads the DOM or screen, it ingests this prompt injection directly.
We demonstrate this exact attack vector and how to sandbox against it in Browser Agents Are a Prompt-Injection Magnet, which builds upon our core AI agent security and prompt injection defense playbook.
(Note: If you are an end-user worried about consumer AI browsers like Atlas or Dia reading your personal data, refer instead to our consumer-focused coverage on consumer AI browser prompt injection).
6. The Best Automation Agents for 2026
Choosing the right tool depends entirely on your target environment. If you need to scrape dynamic web data or automate SaaS workflows, a DOM-aware library like browser-use is highly cost-effective.
If your automation requires interacting with legacy desktop software or Citrix environments, a vision-based computer-use implementation is mandatory.
We benchmarked the leading frameworks for speed, token cost, and reliability. See the full results in our ranking of the best browser automation agents in 2026.
Frequently Asked Questions (FAQ)
A browser agent is an AI system that autonomously drives a web browser to achieve a goal. It perceives the page layout, decides which actions to take (clicking, typing, scrolling), and executes them in a loop without requiring pre-recorded scripts.
A computer-use agent extends beyond the web browser. It uses multimodal vision models to "look" at a screen screenshot and synthetic inputs to move the mouse and use the keyboard, allowing it to control the entire operating system and native applications.
Selenium and traditional RPA rely on hardcoded CSS selectors or fixed screen coordinates. If a button changes color or moves, the script breaks. Browser agents use semantic reasoning (LLMs) to locate elements by their meaning, making them highly resilient to UI changes.
Today, they excel at data extraction from dynamic sites, automated QA testing, filling out complex multi-page forms, and executing routine SaaS workflows (like downloading weekly reports or migrating data between web portals).
They struggle with asynchronous page loading (clicking before a button is ready), dense UIs (miscalculating coordinates), and infinite loops where the LLM repeatedly hallucinates a fix for a failed action instead of throwing an error.
The open-source browser-use library is the current standard for Python/Playwright automation. Claude’s computer use API handles raw OS-level vision control. Google’s Project Mariner represents an upcoming integrated browser-native approach.
No. The agent requires an underlying web automation framework (like Playwright or Puppeteer) to execute actions, and a robust LLM API (like GPT-4o or Claude 3.5 Sonnet) to handle the reasoning and perception loop.
Logins are typically handled by preserving the browser context (cookies/session state) between runs. CAPTCHAs remain a hard blocker for most autonomous agents; best practice dictates pausing the agent to allow a human-in-the-loop to solve it.
Running a computer-use agent directly on your host OS is dangerous due to prompt injection risks. Malicious websites can instruct the agent to delete files or exfiltrate data. Always run them in isolated, ephemeral Docker containers.
The fastest starting point is to install Python, Playwright, and the browser-use library. Define a simple text goal, instantiate the agent with your LLM API key, and run it in non-headless mode so you can watch the agent execute its steps.