How to Detect and Stop Runaway AI Agents
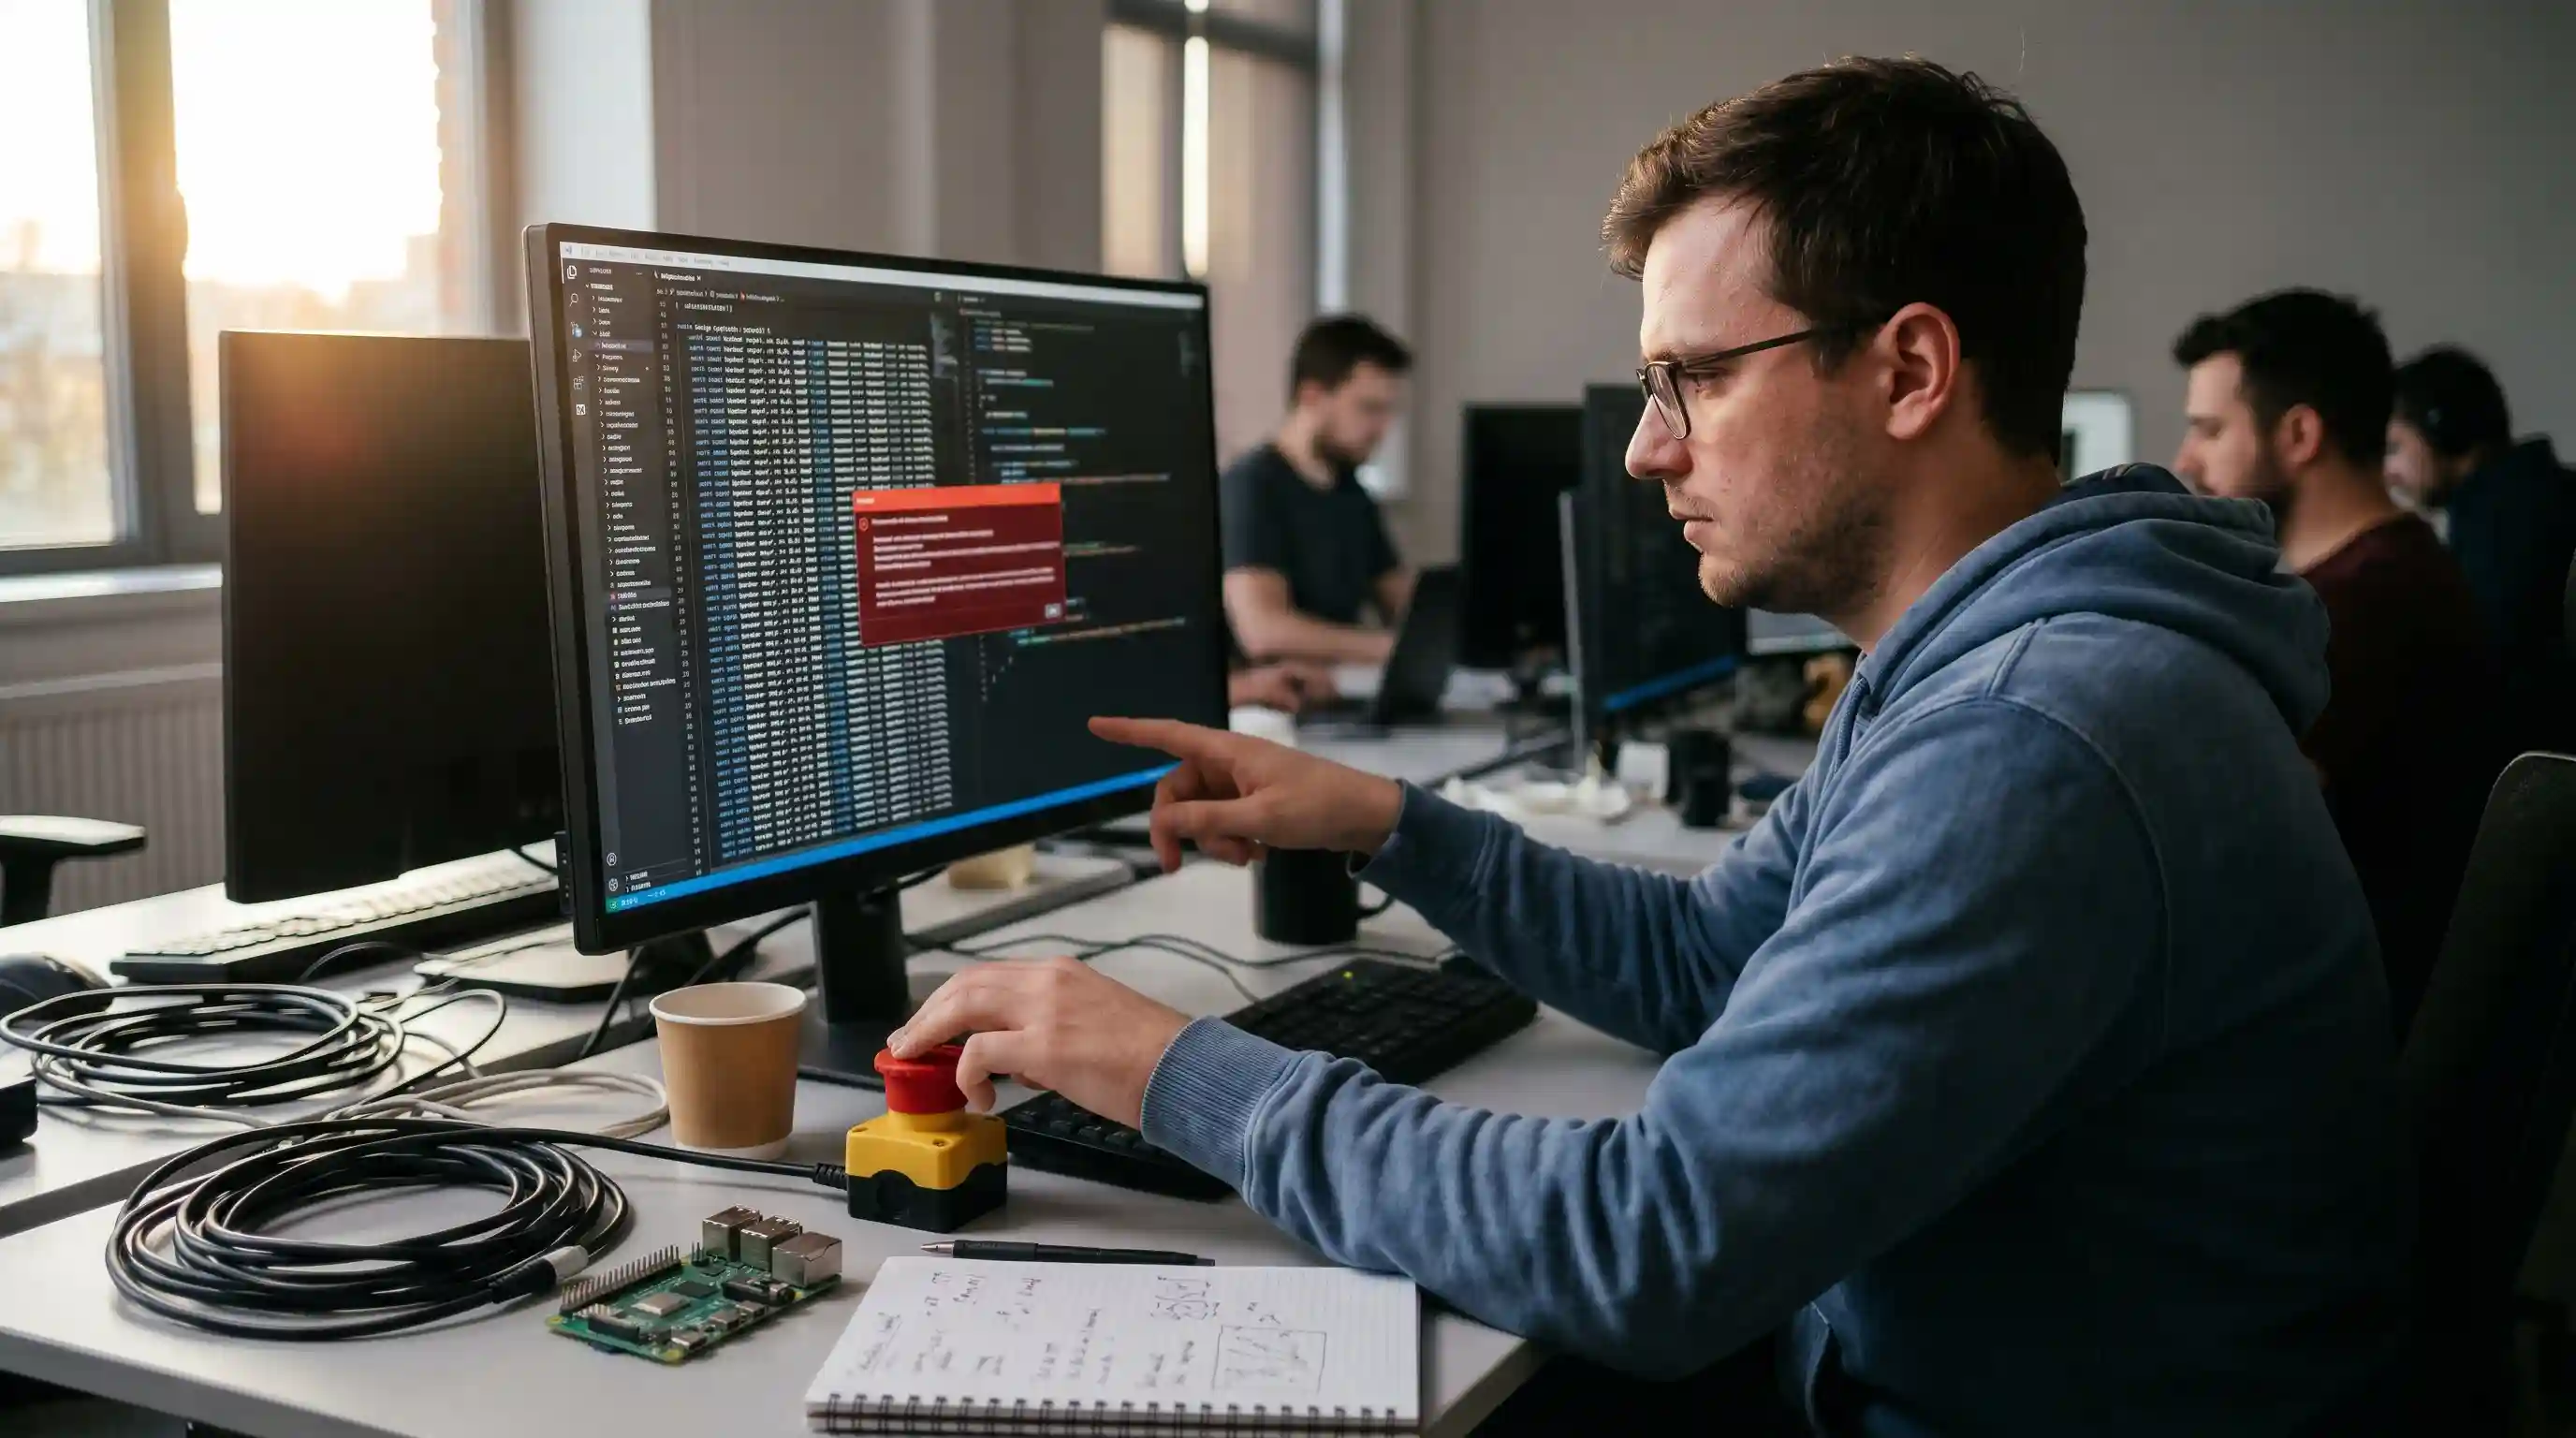
- A runaway AI agent occurs when an autonomous agent enters an infinite loop of recursive tool calls, self-referential prompts, or unhandled exceptions.
- Primary warning signals include exponential token consumption spikes, excessive graph execution depth, and repetitive semantic patterns.
- An automated AI kill switch is mandatory to forcefully terminate execution graphs when predefined cost or step thresholds are crossed.
- Implementing multi-agent circuit breakers prevents a single looping worker from causing cascading failures across an entire enterprise swarm.
The most expensive failure mode in production AI is the runaway loop. A worker agent encounters an error, the LLM hallucinates a fix that causes another error, and the agent rapidly loops—burning thousands of dollars in API tokens per minute.
To survive this, engineering teams must deploy advanced guardian agents equipped with real-time circuit breakers.
Detecting runaway AI agents before they burn your budget or break production requires shifting from passive logging to active trajectory monitoring. This playbook provides the runtime patterns, thresholds, and kill switches required to secure your autonomous graphs.
What is a Runaway AI Agent? (Anatomy of a Loop)
A runaway agent is the generative AI equivalent of an infinite while loop in traditional software engineering. However, it is much harder to catch with regular tools.
Because the agent continues to send valid HTTP requests to LLM providers, traditional application performance monitoring (APM) tools see 200 OK statuses.
The system appears perfectly healthy on paper, but under the hood, the model is trapped in a reasoning loop, trying the same failing tool strategy over and over.
Early Warning Signals: Catching the Loop Before the Blowout
Engineering teams cannot afford to wait for a monthly invoice to discover a runaway agent. You must monitor runtime metrics at the orchestrator level.
Exponential Token-Cost Blast
The most immediate signal of an agent going off the rails is an anomalous, non-linear spike in token usage within a single session.
When an agent loops, its context window rapidly fills with historical error traces. As a result, each successive loop consumes significantly more input tokens than the last, causing cost accumulation to accelerate exponentially.
Execution Graph Depth and Recursive Trajectories
Every stateful multi-agent system should track its graph depth, which represents the total number of node-to-node transitions within a single session.
If a typical user request completes in 5 to 7 steps, an execution trace reaching 25 steps is a definitive indicator of a recursive loop.
Monitoring software must watch for repetitive semantic patterns, such as an agent invoking the exact same tool with identical parameters multiple times sequentially.
Core Oversight Architecture: Implementing the AI Kill Switch
Detecting a loop is pointless if your system cannot programmatically intervene to stop it. Your orchestration layer must feature an immutable kill switch.
State Checkpoints and Automatic Budget Caps
An effective kill switch relies on state checkpointing. Every time an agent node executes, the supervisor records the cumulative session cost to the shared state.
If the session cost breaches a hard limit—for example, $5.00 for a single user query—the system trips the switch.
Instead of routing to the next worker node, the graph forces a transition to a termination node, saving the state for developer review.
Engineers can learn the exact coding steps to implement these defensive structures by studying our guide on building an AI kill switch.
Circuit Breakers for Autonomous Agent Swarms
In complex corporate networks, a single runaway agent can quickly cause cascading failures across multiple independent downstream systems.
If a customer service agent gets stuck in a loop, it might flood an internal CRM agent with thousands of automated API calls per second, knocking it offline.
Implementing distributed circuit breakers resolves this. When a downstream agent detects an anomalous influx of requests from an upstream worker, it opens the circuit.
This completely severs the inter-agent communication channel, isolating the malfunctioning worker and preserving the integrity of the rest of your system.
To safeguard your broader topology against these multi-agent network avalanches, read our detailed technical architectural breakdown of circuit breakers for autonomous AI agent swarms.
Recovery Playbook: Debugging and Rollback Patterns
Once a kill switch trips and isolates a runaway agent, your engineering team needs a clean recovery playbook.
First, you must identify why the agent failed. This usually involves tracking down unhandled exceptions or hidden tool logic errors.
To prevent these issues from reaching production, teams should implement the diagnostic strategies outlined in our manual on debugging silent tool failures.
Once the root cause is resolved, use your framework's state checkpointers to roll back the state graph to the last known successful node, allowing you to resume execution safely without repeating the entire workflow.
Frequently Asked Questions (FAQ)
A runaway AI agent is an autonomous system that becomes trapped in an infinite loop. This typically happens when the agent encounters an unexpected error and continuously attempts to resolve it by making repetitive LLM calls or tool invocations, consuming massive resources without completing the task.
You can detect loops by monitoring your graph execution depth and checking for repetitive tool calls. If an agent executes the exact same tool with identical arguments multiple times sequentially, or if the total step count crosses a safe threshold, the agent is looping.
Key warning signals include a sudden, exponential spike in token consumption within a single session, a high volume of rapid outbound API requests, and an unusual lengthening of processing time for a routine user prompt.
You must track cumulative token costs inside your application's shared state object. After each node execution, calculate the financial cost of the tokens used and configure a conditional edge that aborts the workflow if the cost exceeds a strict budget limit.
An AI kill switch is a programmatic mechanism that immediately stops an agent's execution. You build it by embedding a conditional evaluation node into your state graph that intercepts the execution path and routes it directly to an END state if budget limits are violated.
Circuit breakers track the rate of failures and requests between interacting agents. If a worker agent starts failing repeatedly or flooding another agent with looping queries, the circuit breaker opens, blocking all further communication to protect the rest of the ecosystem.
A guardian agent can stop a runaway agent almost instantly—typically on the very next step of the graph execution. Because the guardian evaluates the agent's state trajectory at every node transition, it trips the kill switch before a loop can scale.
To roll back bad actions, your system must save persistent state snapshots using database checkpointers. If an agent fails or runs away, you can revert the state to a previous, verified snapshot, undoing the logic chain before restarting the execution.
Traditional APM logging is insufficient because looping agents still return standard HTTP 200 responses. You need specialized semantic observability and agent-tracing tools that can actively parse execution trees, step counts, and token counts per session.
Prevent runaway costs by implementing strict hard caps on maximum graph depth, establishing token budget limits per user session, utilizing rule-based input/output guardrails, and enforcing mandatory human-in-the-loop approval gates for all high-risk or external tools.