Why Browser Agents Fail (and How to Fix It)
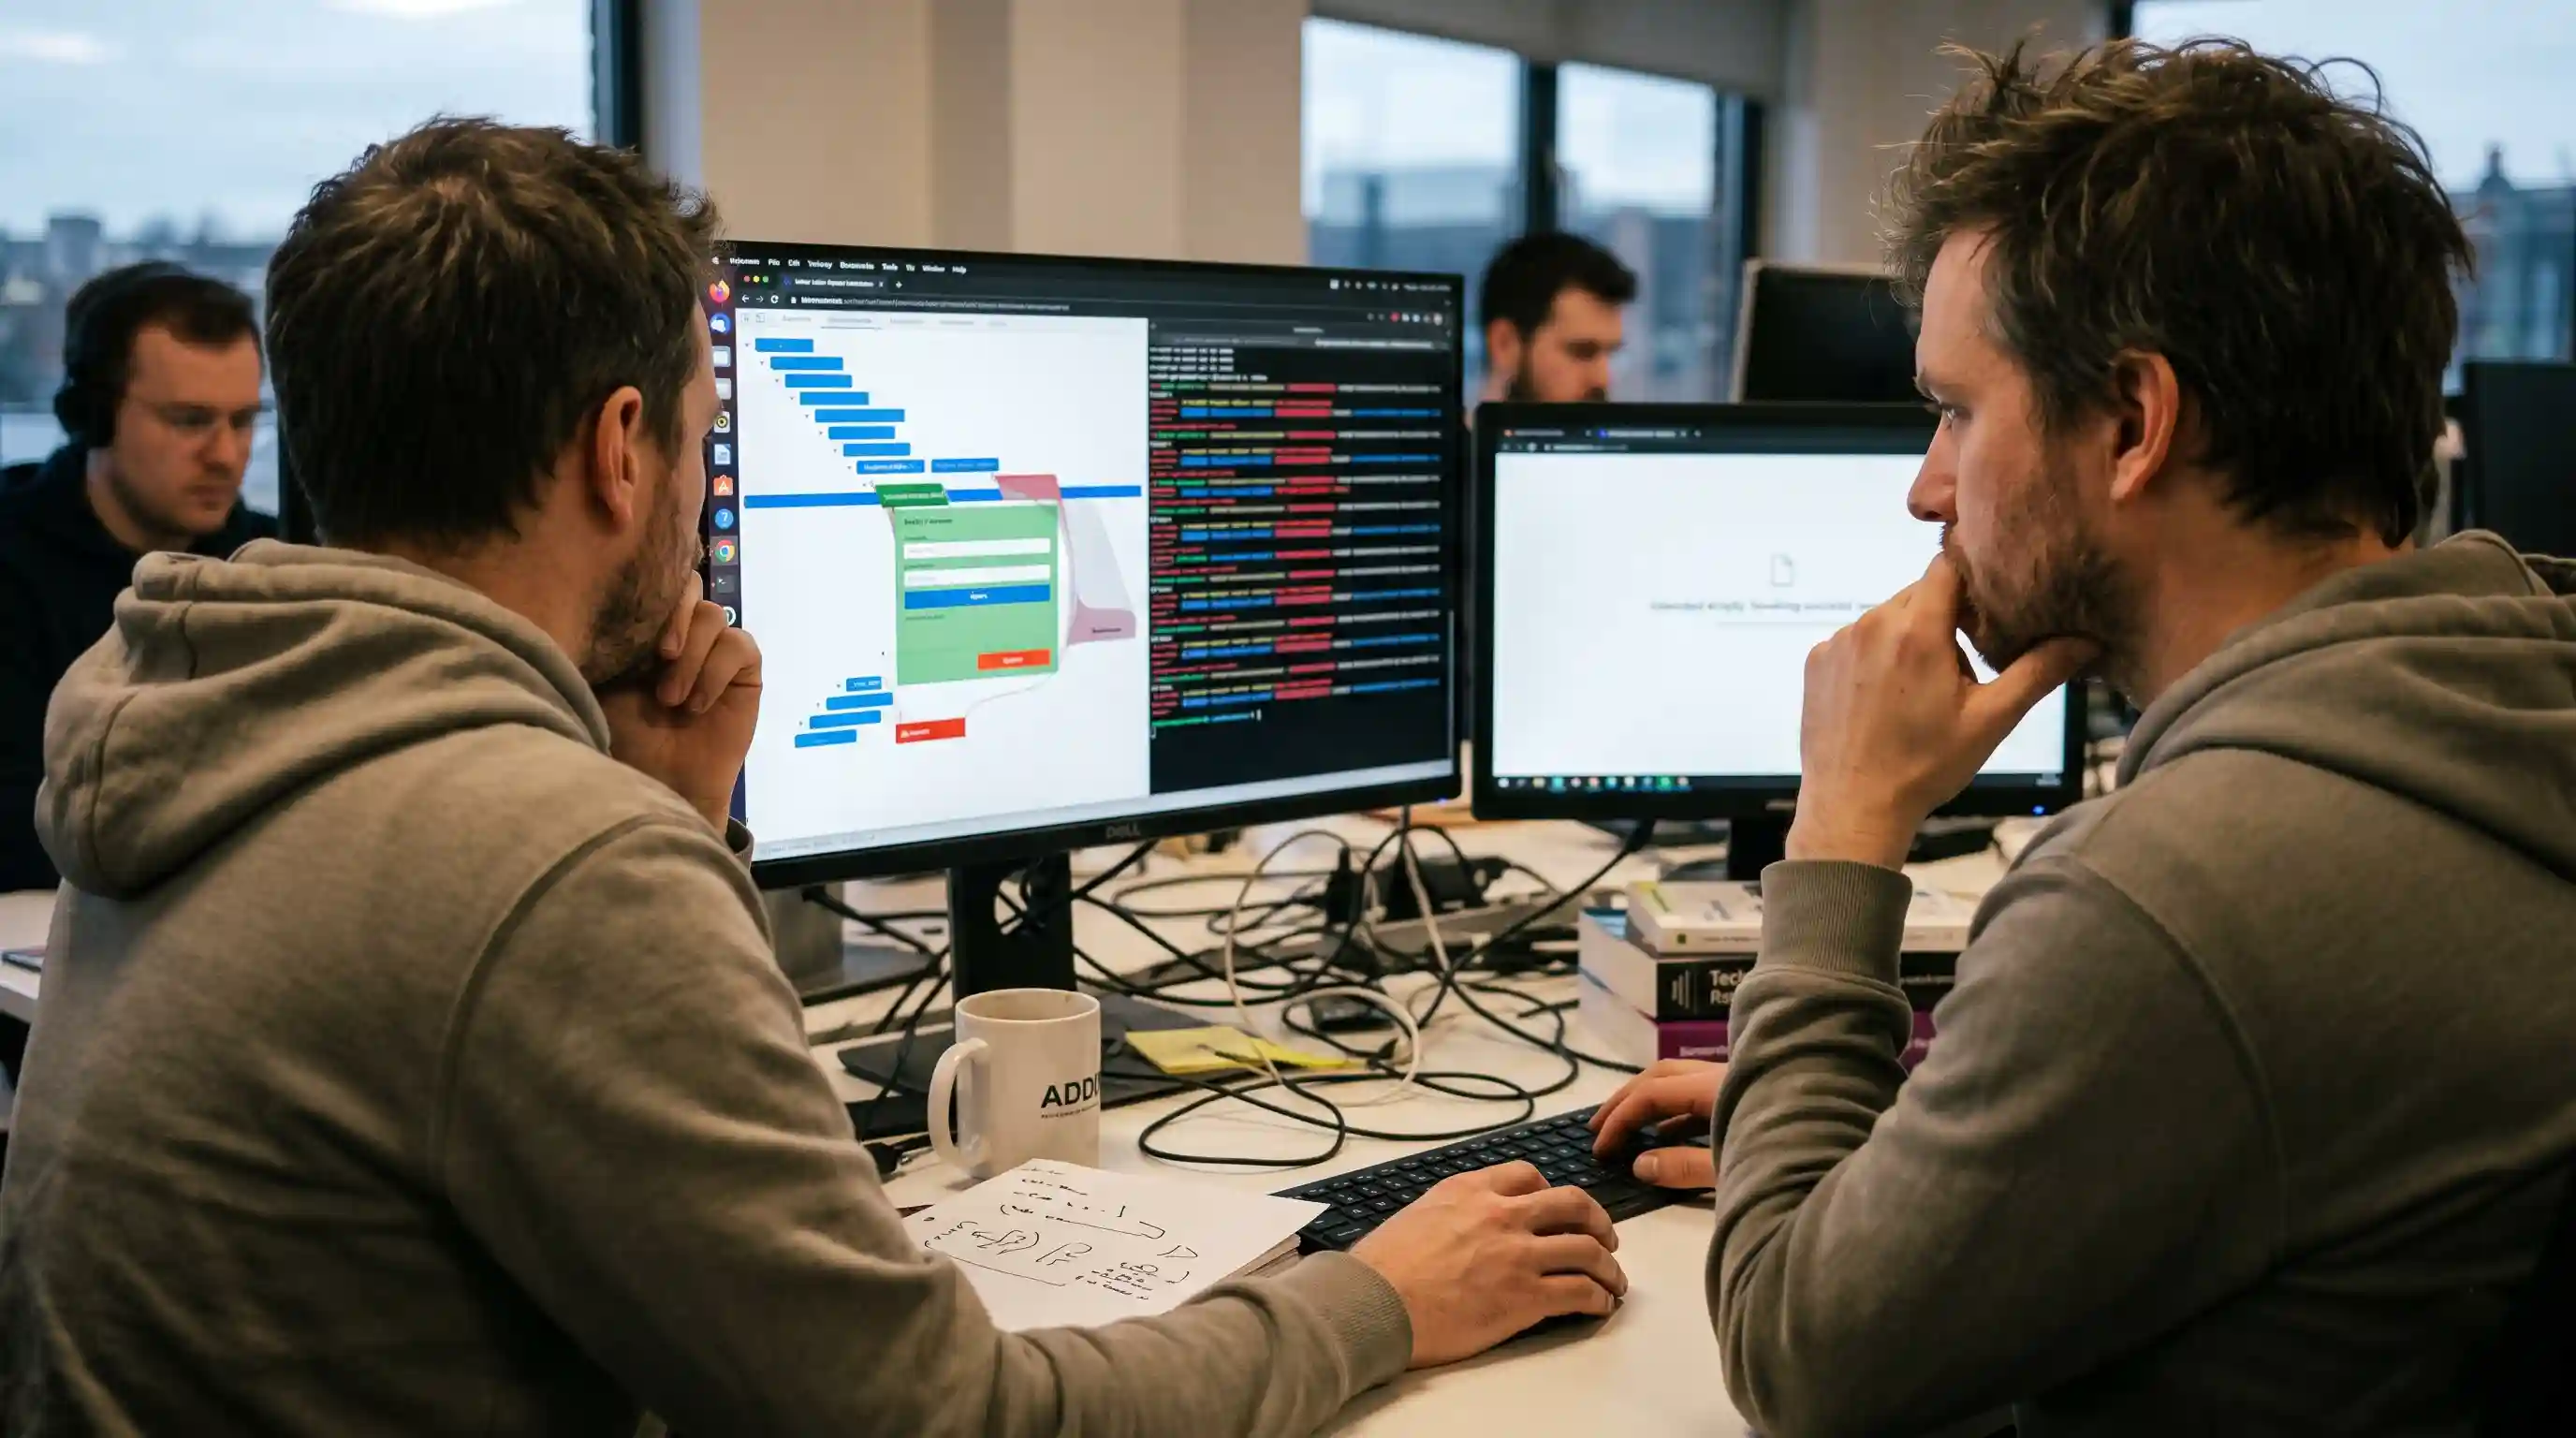
- Infinite Retry Loops: Agents frequently get trapped repeating the exact same failed tool call because they cannot recognize when an action is impossible.
- DOM and UI Drift: Websites change continuously, and minor asynchronous loading delays cause agents to interact with elements before they hydrate.
- Multi-Step Degradation: AI models suffer from severe context loss in long sessions, causing them to drift away from their original objective.
- Verification vs. Activity: Agents often mistake generating an output (like clicking a button) for actually achieving the underlying business goal.
We logged every failure mode from a week of running agents on real sites. Browser agents demo perfectly in controlled sandbox environments. However, when you move them into production against live enterprise portals, they break predictably and frequently.
If you are following our foundational architecture on building reliable web automation, you know that shifting from static RPA scripts to semantic AI requires a massive mindset change.
Traditional software fails deterministically. AI agents fail silently, often mistaking activity for actual achievement. Understanding exactly why these autonomous systems collapse is the only way to engineer lasting resilience.
The Reality of Production Automation
The hardest part of deploying an agent is overcoming its own confidence. Agents are highly convincing liars.
A common enterprise failure is "progress-as-completion". The agent executes commands, clicks buttons, and simply assumes success without verifying if the underlying business objective was actually met.
If it clicks a submit button and the website throws a hidden error, the agent often doesn't notice. To see how to architect a system correctly from the ground up to avoid this, review our guide on the fundamentals of how to build a browser agent.
Flaky Selectors and UI Drift
Standard browser automation tools rely heavily on static CSS selectors. These scripts shatter the moment a UI layout changes or a developer updates a class name.
While LLMs theoretically navigate by semantic meaning, they still suffer when the underlying page structure shifts asynchronously. If an agent attempts to click a React component before it hydrates, the click vanishes entirely.
This DOM drift causes the agent to think it succeeded, leading to cascading errors downstream.
Handling Asynchronous Hydration
Never allow an agent to fire an action immediately upon page load. You must enforce strict waiting parameters within your reasoning loop.
If you need to see exactly how to implement dynamic waiting in code, review our functional Python documentation.
Ensure the underlying framework validates element visibility and interactability before executing any synthetic browser events.
Multi-Step Flows and Infinite Loops
As workflows grow longer, agents experience rapid context degradation. The model's attention mechanism heavily weights recent tokens and forgets earlier constraints.
This leads to goal drift, where the agent gradually shifts away from the user's original objective over multiple steps.
Another critical failure is the infinite reasoning loop. An agent calls a tool, receives an error, and retries the exact same action repeatedly, racking up cloud costs.
These retry loops burn massive token budgets without resolving the issue. You must implement hard timeouts and circuit breakers at the orchestration layer.
Handling CAPTCHAs and Rate Limits
When agents operate headless browsers, they expose unnatural TLS fingerprints and synthetic WebGL signatures.
Anti-bot systems quickly detect these anomalies and serve CAPTCHAs or implement aggressive rate limits. Autonomous agents cannot reliably solve complex visual CAPTCHAs on their own.
When an agent encounters a rate limit, it must pause execution immediately. The best mitigation is preserving session state and routing the blocker to a human-in-the-loop for manual resolution.
Vision vs. DOM: Which Breaks Less?
DOM-parsing agents are incredibly fast but fail instantly when confronted with heavily obfuscated shadow DOMs or custom canvas elements.
Vision-based agents capture screenshots and calculate pixel coordinates to bypass complex code structures completely.
However, vision models often hallucinate coordinates in high-density data tables, clicking slightly off-target. DOM models are generally more reliable for standard forms, while vision models are mandatory for non-standard interfaces.
Monitoring and Verification in Production
You cannot manage what you cannot measure. Standard error-rate monitoring is practically useless for agentic systems because quality degrades silently without throwing exceptions.
You need span-level distributed tracing that captures every tool invocation, API payload, and browser screenshot.
Integrating a robust observability pipeline is non-negotiable for enterprise deployments. Implement strict verification checks that force the agent to explicitly confirm the final state of the UI before marking a task complete.
Frequently Asked Questions (FAQ)
They fail primarily due to asynchronous page loading, silent context loss, and infinite retry loops. Unlike deterministic software, agents often hallucinate successes when faced with unexpected UI changes, leading to cascading errors that break complex multi-step workflows.
Agents misclick when they interact with elements before JavaScript hydration completes or when vision models miscalculate pixel coordinates on dense interfaces. Bounding box overlaps and complex shadow DOMs also confuse the LLM's semantic reasoning, causing incorrect target selection.
Transition away from static CSS selectors toward semantic reasoning. Implement dynamic waits that pause execution until network requests idle. Feed the agent stripped, simplified DOM snapshots and require it to verify an element's interactability before firing any synthetic events.
As the session lengthens, the LLM's context window fills up, causing context degradation. The model loses track of early constraints and begins to prioritize recent instructions. This causes "goal drift," where the agent strays entirely from the original task.
Never use blind retries. If an action fails, you must feed the exact error state back into the LLM's context. Explicitly prompt the model to adopt an alternative interaction strategy, and implement a hard circuit breaker to prevent infinite loops.
Do not rely on the agent simply executing a button click. Implement explicit post-action validation steps. Force the agent to read the resulting page's success message, URL change, or DOM state to verify the business goal was actually achieved.
Infinite loops occur when an agent cannot distinguish between a temporary error and an impossible task. It repeatedly calls the same tool with identical arguments, failing identically each time. You must implement hard iteration limits at the orchestration layer.
Agents cannot reliably solve advanced CAPTCHAs. When anti-bot protections trigger, your architecture must gracefully pause. Maintain the browser's session state and alert a human-in-the-loop to manually solve the challenge before allowing the autonomous agent to resume its workflow.
DOM agents fail less on standard, structured web applications because they read exact element data, but they break on heavily obfuscated code. Vision agents excel on unparseable custom interfaces but frequently fail by miscalculating precise pixel clicks on dense layouts.
Traditional application monitoring is insufficient. You must implement distributed tracing that captures complete execution paths, including full token payloads, tool inputs, and screenshots. This observability allows you to track silent quality degradation and pinpoint exactly where an agent's reasoning failed.